MCP Toolbox for Databases: An Open Toolchain for Connecting Agents to Enterprise Data
# MCP Toolbox for Databases: An Open Toolchain for Connecting Agents to Enterprise Data
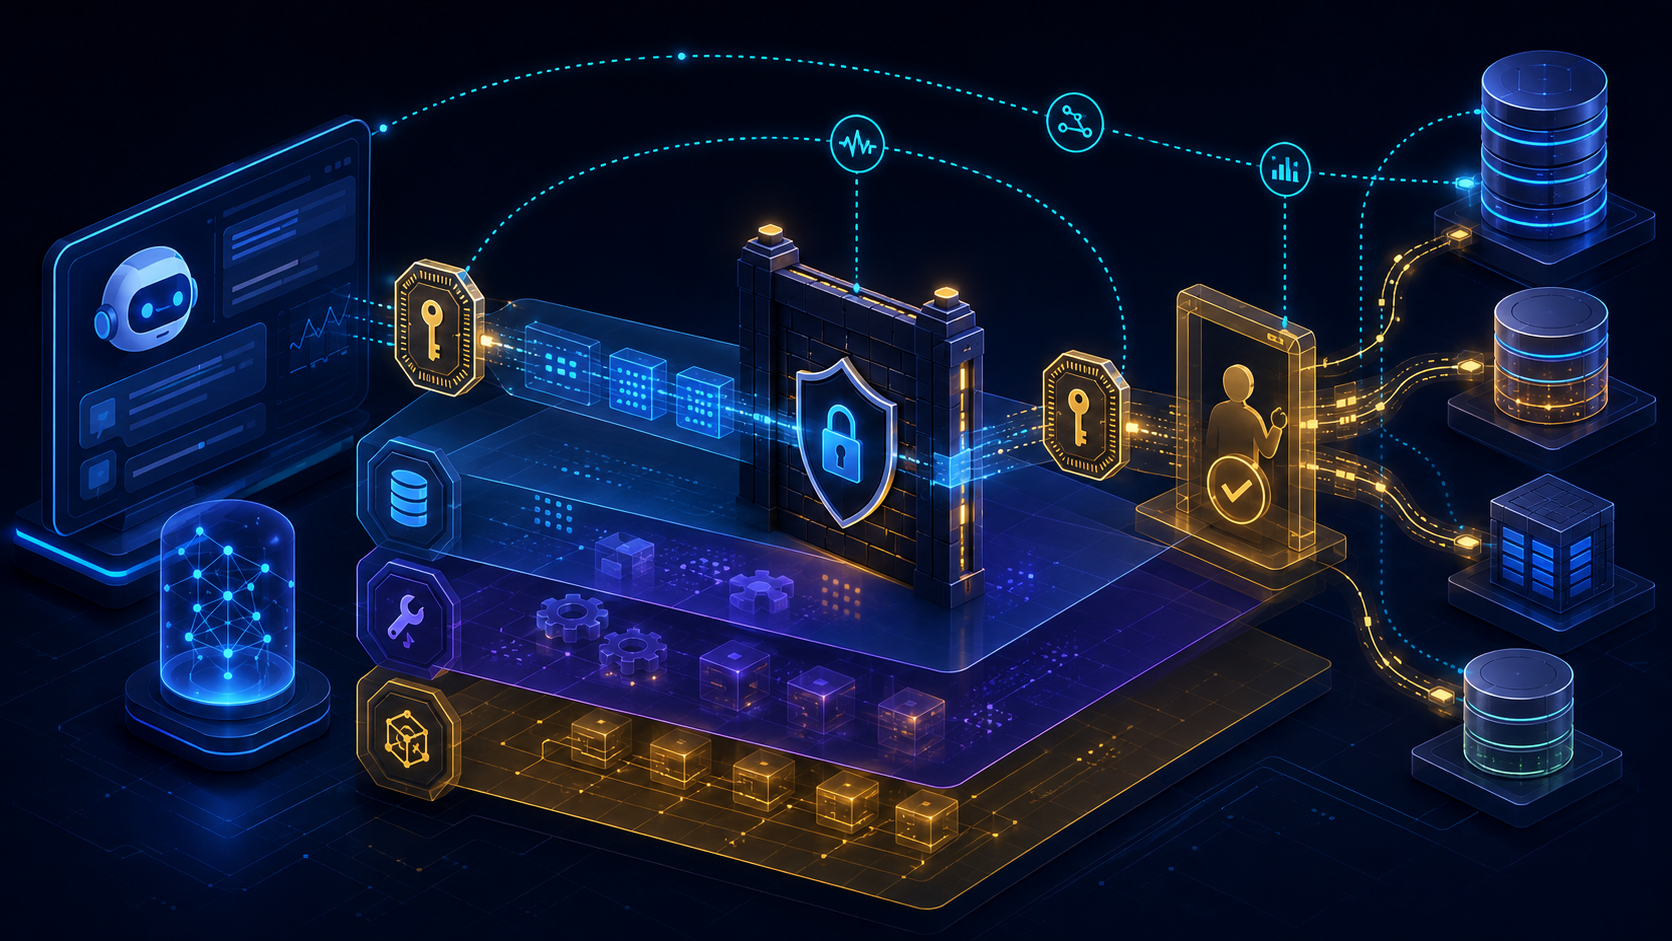
When an agent starts accessing enterprise data, the hard part is usually not adding another model. The hard part is turning database access into a controlled, observable, maintainable tool interface. Letting a model generate arbitrary SQL creates engineering risks: excessive permissions, unpredictable queries, unclear connection lifecycles, and little traceability when something goes wrong.
Google's open-source **MCP Toolbox for Databases** addresses the problem at the database-tool layer. It is both a Model Context Protocol (MCP) server and a custom tool framework. It provides prebuilt tools for connecting to databases, while also letting teams define sources, parameterized queries, toolsets, and prompts in `tools.yaml` for use by Gemini CLI, Claude Code, Codex, Agent Development Kit (ADK), LangChain, LlamaIndex, or a custom agent.
This article does not present it as magic that lets a model manage databases safely by itself. Based on the repository, official documentation, and executable configuration examples, it explains the project's practical position: how it packages database capabilities as MCP tools, how to limit what an agent can do, when it is a good fit, and which governance controls remain the adopting team's responsibility.
> Research snapshot: September 3, 2026. The repository had approximately 16,303 GitHub stars, its latest release was `v1.10.0`, and it used the Apache-2.0 license at the time of review. Stars and versions change; use the official project pages for current values.
## The short version: it is a tool layer, not an ORM
MCP Toolbox is not a replacement for PostgreSQL, BigQuery, or MongoDB, and it is not another ORM. It sits between an agent and its data sources, turning database capabilities into tools that an agent can discover, load, and invoke.
The official design supports two modes:
1. **Prebuilt MCP server:** Start existing tools with `--prebuilt=` so a compatible IDE or CLI can explore schemas and perform standard, controlled database operations quickly.
2. **Custom tool framework:** Define sources, parameters, and SQL explicitly in `tools.yaml`, then expose domain logic through stable interfaces to production agents.
This separation matters. Prebuilt tools are useful for exploration and rapid validation. Custom tools move tool names, descriptions, parameters, and query logic out of model prompts and into artifacts that can be reviewed, tested, and versioned.
## Architecture: sources, tools, toolsets, and prompts
MCP Toolbox configuration is not a prompt filled with arbitrary SQL. It is composed of several explicit resource types.
### Source: the database boundary
A `source` describes a data source that Toolbox may access, such as PostgreSQL:
```yaml
kind: source
name: analytics-db
type: postgres
host: ${DB_HOST}
port: 5432
database: ${DB_NAME}
user: ${DB_USER}
password: ${DB_PASSWORD}
```
The official documentation lists integrations for Google Cloud and third-party databases, including AlloyDB, BigQuery, Cloud SQL, Spanner, Firestore, PostgreSQL, MySQL, MariaDB, SQL Server, Oracle, MongoDB, Redis, Elasticsearch, CockroachDB, ClickHouse, Couchbase, Neo4j, Snowflake, and Trino. The current prebuilt-tools reference is the authority for the exact integrations and tool names available in a given release.
The operational rule is more important than the YAML: do not put credentials directly in the configuration file. The official quickstart recommends `${ENV_NAME}` replacement; production deployments should additionally use a Secret Manager, short-lived credentials, and a least-privilege database role.
### Tool: a stable action interface
A `tool` defines one action an agent may take. This example exposes a parameterized hotel-name query:
```yaml
kind: tool
name: search-hotels-by-name
type: postgres-sql
source: analytics-db
description: Search for hotels based on name.
parameters:
- name: name
type: string
description: The name of the hotel.
statement: SELECT * FROM hotels WHERE name ILIKE '%' || $1 || '%';
```
The model does not receive a blank instruction to invent SQL. It receives a tool name, purpose, parameters, and result. That is not an automatic security review, but it creates a reviewable control surface: teams can restrict columns, fix `WHERE` clauses, add pagination, and give write operations separate tools.
Read and write tools should generally be designed separately. `search-hotels-by-name` can use a read-only role, while `book-hotel` or `update-hotel` should have explicit business rules, authorization, approval, or transaction boundaries. MCP makes invocation easy; it does not mean an agent should receive every database write permission.
### Toolset: control the exposed capability set
A `toolset` groups tools that can be loaded together:
```yaml
kind: toolset
name: booking-read-tools
tools:
- search-hotels-by-name
- search-hotels-by-location
```
When different agents or applications need different capabilities, a toolset is preferable to exposing every database tool at once. A support agent may only need order lookup, an analytics agent may need reporting queries, and an internal developer tool may need schema exploration. Toolsets also reduce context size and incorrect tool selection.
### Prompt: reusable guidance in configuration
Toolbox can define reusable prompts in configuration, such as a code-review or data-analysis instruction with parameters. This keeps guidance consistent across calls. A prompt is not an authorization system, however. Sensitive-data protection and tool authorization still belong to auth services, database roles, and the application layer together.
## Two startup paths: quick validation and production deployment
### Validate the integration with prebuilt tools
For teams that first want to confirm that an MCP client can see database tools, the official README provides an `npx` startup path. The following connects PostgreSQL prebuilt tools to an MCP client:
```json
{
"mcpServers": {
"toolbox-postgres": {
"command": "npx",
"args": [
"-y",
"@toolbox-sdk/server",
"--prebuilt=postgres",
"--stdio"
],
"env": {
"POSTGRES_HOST": "127.0.0.1",
"POSTGRES_PORT": "5432",
"POSTGRES_DATABASE": "toolbox_db",
"POSTGRES_USER": "readonly_user",
"POSTGRES_PASSWORD": "${POSTGRES_PASSWORD}"
}
}
}
}
```
`--prebuilt=postgres` loads PostgreSQL's prebuilt tools. `--prebuilt=postgres/data` can load a narrower toolset. Database integrations and tool names change over time, so consult the release-specific reference before treating a README example as a permanent API contract.
The project also notes that `npx` prioritizes convenience. A production deployment should use the official binary or container image and pin the version rather than unconditionally using `latest`.
### Build domain tools with `tools.yaml`
The custom-tool workflow is to define a source, define a tool, define the toolset, and start the server:
```bash
./toolbox --config tools.yaml
```
The convenience path is also available:
```bash
npx @toolbox-sdk/server --config tools.yaml
```
For a booking service, separate read and write capabilities and expose only the needed toolset:
```yaml
kind: source
name: booking-db
type: postgres
host: ${BOOKING_DB_HOST}
port: 5432
database: ${BOOKING_DB_NAME}
user: ${BOOKING_DB_USER}
password: ${BOOKING_DB_PASSWORD}
---
kind: tool
name: find-booking
type: postgres-sql
source: booking-db
description: Find a booking by its public confirmation code.
parameters:
- name: confirmation_code
type: string
description: Public booking confirmation code.
statement: >-
SELECT id, status, checkin_date, checkout_date
FROM bookings
WHERE confirmation_code = $1
LIMIT 1;
---
kind: toolset
name: customer-support
tools:
- find-booking
```
The important part is not YAML itself. It is that the tool contract becomes reviewable: source name, SQL, input type, description, and exposure scope can all live in Git. Teams still need SQL migrations, integration tests, query timeouts, result limits, and sensitive-column masking; Toolbox does not complete all data governance for you.
## Integrating with an agent: MCP or an SDK
With an existing MCP client, Toolbox runs as an independent MCP server. If you are building your own agent application, the project also provides SDKs:
- Python: `toolbox-core`, with ADK, LangChain, and LlamaIndex integrations.
- JavaScript/TypeScript: `@toolbox-sdk/core` and framework integrations.
- Go: an official Go SDK with ADK, Genkit, and LangChain quickstarts.
- Java: an official Java SDK.
The minimal Python core call looks like this:
```python
import asyncio
from toolbox_core import ToolboxClient
async def main():
async with ToolboxClient("http://127.0.0.1:5000") as toolbox:
tool = await toolbox.load_tool("find-booking")
result = await tool(confirmation_code="ABC123")
print(result)
if __name__ == "__main__":
asyncio.run(main())
```
The Python core SDK uses an asynchronous client for loading and invoking tools and supports context-manager lifecycle management for its HTTP session. If you do not use `async with`, explicitly call `close()` in a `finally` block. This small detail affects the stability of long-running services.
The SDK also supports multiple MCP-over-HTTP protocol versions and negotiation. When compatibility with an older client matters, explicitly select a protocol. When strict pinning is required, pass a list containing only one version. Upgrades can then be tested instead of discovered in production.
## Security: having a capability does not mean exposing it
The official documentation exposes several security layers, which is where MCP Toolbox offers more engineering structure than a simple database question-answering prompt.
### Generic OIDC and MCP Authorization
The Generic Auth Service can integrate with an OIDC-compliant identity provider. Toolbox can discover or use a configured `authorizationServer` to obtain JWKS and validate JWT signatures, expiration, audience, and scopes. With `mcpEnabled: true`, it validates the standard `Authorization: Bearer` token on MCP endpoints and can also handle opaque-token introspection.
The configuration concept is:
```yaml
kind: authService
name: company-oidc
type: generic
audience: ${MCP_AUDIENCE}
authorizationServer: https://idp.example.com
mcpEnabled: true
scopesRequired:
- mcp:tools
```
The official MCP authorization guide says that enabling this mode automatically provides a Protected Resource Metadata endpoint. Deployment also requires an absolute `TOOLBOX_URL` so clients can identify the protected resource. On Cloud Run, Cloud Run IAM tokens and Toolbox MCP bearer tokens may belong to different authorization layers and should not be conflated.
### Tool-level authorization and claim binding
Auth services can protect the entire MCP server or be used with `authRequired` and `scopesRequired` on individual tools. Token claims can also populate parameters. This enables different scopes for different tools on the same server instead of relying on one coarse global permission.
Authorization configuration does not remove prompt injection, data leakage, or incorrect tool selection. The official security documentation explicitly identifies prompt injection, jailbreaks, and sensitive-data leakage as risks to address. A production design should still include:
- Separate database roles for read and write tools.
- Human confirmation or business approval for writes and expensive queries.
- Independent monitoring for SQL shape, result size, timeouts, and rate limits.
- Views, masking, or column-level permissions for sensitive fields; do not rely on the model simply not asking.
- Narrow schema and tool exposure instead of giving every agent the entire database surface.
## Observability and deployment: from a local demo to a service
The README lists connection pooling, integrated authentication, and OpenTelemetry metrics and tracing as built-in capabilities. Their value is practical: when an agent response is slow or a tool fails, a team can trace the operation through the MCP call, tool execution, and database query instead of seeing only a chat-level error.
The project provides binary, container-image, and Docker Compose deployment paths. Its Docker Compose example runs Toolbox with PostgreSQL, normally exposing the service on port `5000`. For production:
1. Pin Toolbox and database image versions instead of using a floating `latest`.
2. Separate `tools.yaml` from secrets and inject secrets through a mount or Secret Manager.
3. Keep database connectivity on a private or controlled network, and put TLS, identity, and rate limiting in front of the MCP endpoint.
4. Configure health checks, timeouts, connection-pool limits, and graceful shutdown.
5. Correlate client, tool, and database fields in OpenTelemetry, while preventing tokens and sensitive results from entering spans.
The tool layer can tell you what happened; it cannot decide whether a query is commercially or operationally appropriate. Data quality, cost control, and business authorization remain application-team responsibilities.
## Who should use it, and who should not?
### Good fits
- A team already uses MCP clients and wants a consistent way to connect multiple databases to IDEs or agents.
- Natural-language operations need to be constrained to a fixed, reviewable tool set.
- The same database tools should be reused by ADK, LangChain, LlamaIndex, and multiple custom applications.
- The team needs service-level authentication, scopes, OpenTelemetry, or connection pooling.
- The team wants to begin with prebuilt tools, then turn high-risk operations into narrower custom toolsets.
### Poor fits without additional architecture
- A one-off offline analysis where an existing data pipeline is simpler.
- A team that cannot manage database permissions, secrets, networking, and observability but plans to expose a production database directly to an agent.
- Complex transactional workflows, strict consistency requirements, or high-volume batch processing that belong in a conventional service or workflow engine, with only a few safe actions exposed as tools.
- A desire for an arbitrary SQL generator. Toolbox is most valuable when arbitrary capability is reduced to reviewable tools, not amplified.
## Adoption checklist
Before connecting MCP Toolbox to production, reduce risk in this order:
- [ ] Start with one read-only, low-sensitivity data source.
- [ ] Begin with a minimal toolset instead of loading the entire database.
- [ ] Use environment variables or secrets; never commit plaintext credentials.
- [ ] Give every tool a clear description, input type, result limit, and timeout.
- [ ] Use separate database roles and scopes for read, write, and administrative functions.
- [ ] Add confirmation, idempotency, and audit logs to high-risk tools.
- [ ] Test MCP protocol versions, SDK session cleanup, and network retry behavior.
- [ ] Pin binary/container versions and create compatibility tests before upgrades.
- [ ] Verify that traces, metrics, and logs contain no tokens, passwords, or sensitive data.
- [ ] Red-team scenarios in which prompt injection could manipulate tool selection.
## Conclusion
MCP Toolbox for Databases is worth watching not merely because it lets an agent query a database, but because it decomposes database capabilities into composable engineering resources: sources, tools, toolsets, auth, and SDKs. MCP becomes more than a list of functions handed to a model; it can become a versioned, authorized, observable tool layer with explicit boundaries.
The practical adoption path is to validate the integration with prebuilt tools, turn high-value queries into stable tools in `tools.yaml`, and then add least-privilege database roles, MCP authorization, approvals, and observability. With that governance work, Toolbox can shorten the distance between agents and enterprise data. Without it, MCP simply exposes existing data-security problems faster.
## References
- GitHub:
- Official documentation:
- Official Generic OIDC Auth guide:
- Official MCP Authorization guide:
- Official Python Core SDK guide: