AnythingLLM: A Self-Hosted Workspace for Private Knowledge Bases, RAG, and AI Agents
AnythingLLM: A Self-Hosted Workspace for Private Knowledge Bases, RAG, and AI Agents
When a team starts bringing large language models into daily work, the real question is usually not whether the model can chat. It is whether the model can reliably use the company's own files, tools, and permission boundaries. Connecting a model API to a chat interface solves only the most visible layer of interaction. File parsing, retrieval, citations, multi-user isolation, model switching, Agent tools, and operational maintenance quickly turn into a complete product.
AnythingLLM is an open-source application built for this gap. It brings document chat, RAG, AI Agents, model providers, vector databases, and multi-user capabilities into a workspace that can run with Docker or as a desktop application. This article does not treat it as "yet another ChatGPT interface." Instead, it examines from an engineering perspective how it assembles a usable knowledge workflow, which situations benefit from rapid adoption, and which areas still require a team to establish its own governance.
The short version: it reduces integration cost
AnythingLLM's value is not that it invents a new foundation model. Its value is that it integrates components that teams would otherwise have to assemble themselves into an operational application layer. The official README describes it as an all-in-one AI application that supports local or cloud LLMs, document imports, built-in Agents, vector databases, and multi-user capabilities. The project is released under the MIT License and offers Desktop, Docker, and other deployment paths.
That positioning matters. If you only want to test a model, the model provider's Playground will be faster. If you are building your own SaaS product, you may need a more specialized workflow engine, observability, billing, and tenant isolation. AnythingLLM's sweet spot is helping individuals, internal teams, and product groups running rapid validation obtain a self-hosted, extensible AI entry point that can connect to documents and tools without first building an entire platform-engineering stack.
At the time of verification, GitHub showed more than 64,000 stars for the project, with its latest push occurring in August 2026. That satisfies the conditions of a high-star, actively maintained candidate. Star count is not a quality guarantee, but it does indicate substantial attention from users and contributors. What is worth examining is which boundary problems the product handles directly.
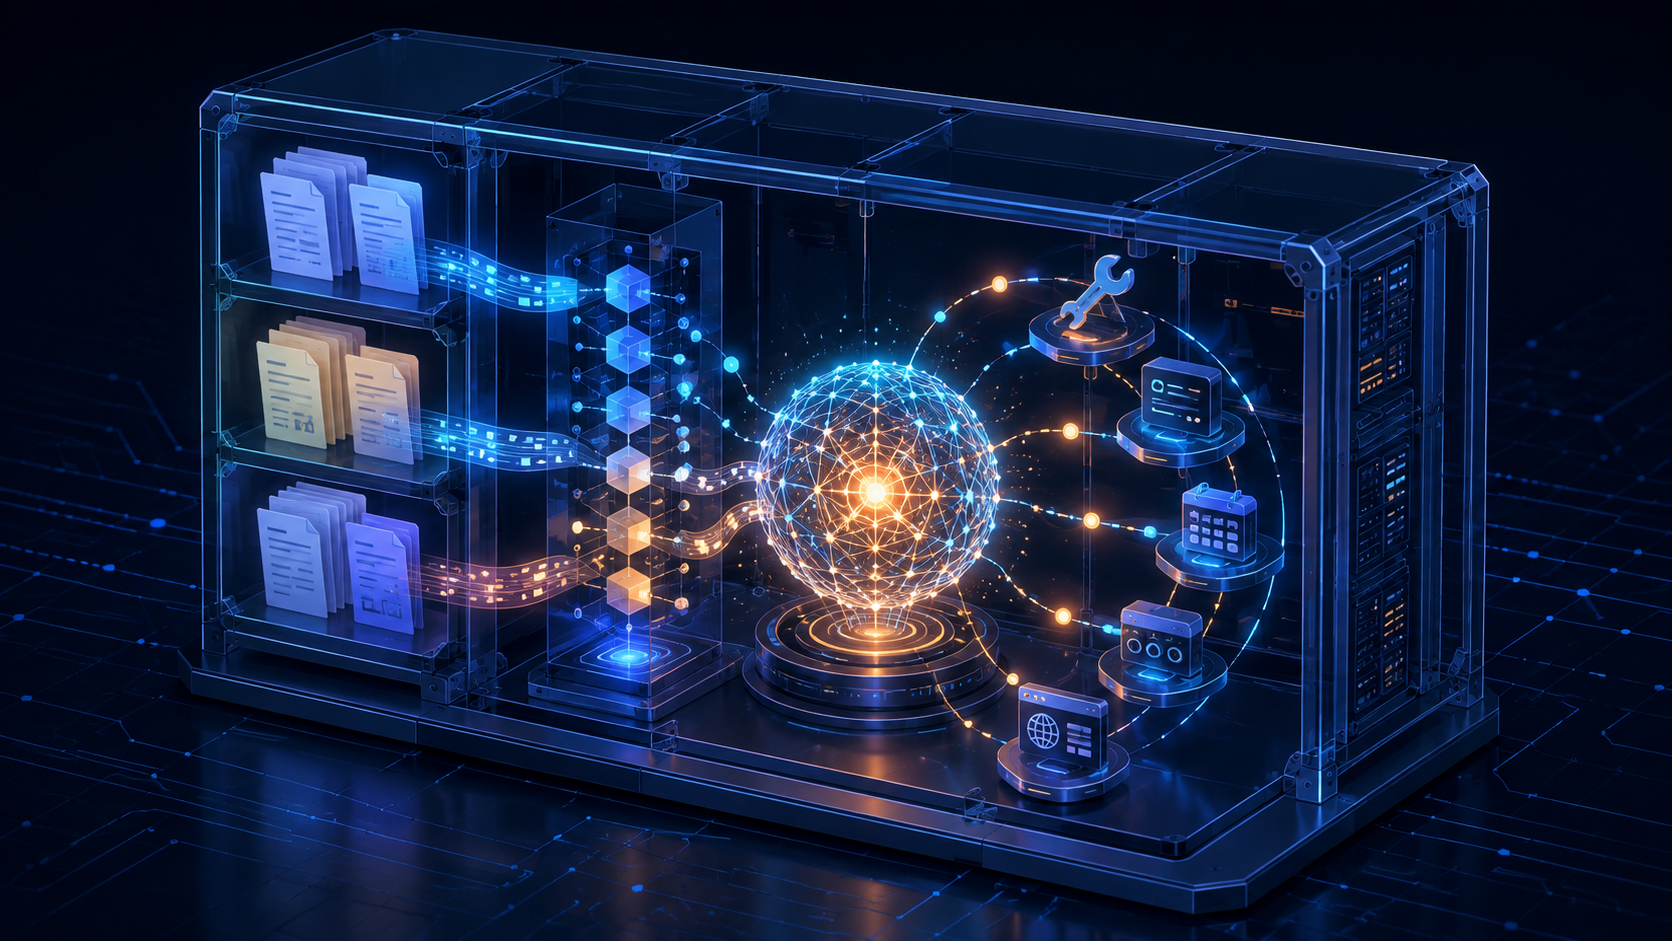
A complete document-question-answering data flow
Document Q&A is often simplified to "put a PDF into a vector database and search for similar passages." In practice, a usable RAG system includes ingestion, parsing, chunking, embedding, indexing, retrieval, context assembly, and answer presentation. If any one of these stages is unstable, the result may be incorrectly blamed on the model's capabilities.
AnythingLLM packages these steps around the concept of a workspace. Users can add PDF, TXT, DOCX, and other files to a workspace, after which the system processes the content through its document collector and builds context for the LLM. The chat interface displays source citations, allowing users to verify where an answer came from instead of accepting a plausible-looking generated response without checking it.
From an architectural perspective, one Q&A request can be abstracted into the following flow:
1. The user uploads files, and the collector parses and cleans them.
2. The files are split into retrieval-friendly chunks and converted into vectors by an embedder.
3. The vectors and original chunks are written to the selected vector database.
4. When the user asks a question, the system retrieves relevant chunks and combines them with the question as context.
5. The LLM generates an answer from that context while the interface presents sources and citations.
The official README lists LanceDB as the default vector database and names PGVector, Chroma, Qdrant, Weaviate, Milvus, and Pinecone as other options. This lets a prototype start with fewer external services and change its storage layer later as data volume, query concurrency, or existing infrastructure evolves. However, support for multiple databases does not mean that their latency, indexing strategies, and backup methods are equivalent. Before production, they still need to be evaluated against the team's own documents and query distribution.
Workspace is the product abstraction for context isolation
A simple chat history is not enough for enterprise knowledge management because documents from different subjects can contaminate one another's context. AnythingLLM uses workspaces to group files, conversations, and settings, allowing a product manual, legal contracts, and an engineering runbook to maintain separate knowledge boundaries.
This abstraction also makes permissions easier to reason about: who can enter a workspace, who can upload files, who can use Agents, and which models may be selected. The Docker version provides multi-user and permission-management capabilities, making it suitable as an internal service rather than a tool used only on one engineer's computer.
A workspace should not be mistaken for automatic data governance. During adoption, at least three questions must be answered:
- When a file is deleted, are the original file, chunks, and vector index removed together?
- After permissions change, could existing conversations, citations, or caches still expose the data?
- During backup and migration, do the vector database, file storage, configuration, and secrets follow a consistent lifecycle?
The UI cannot fully solve these questions. AnythingLLM provides a reasonable product entry point, but the organization still needs operating rules for data classification, retention periods, deletion procedures, and audit ownership.
From RAG to Agents: more tools are not always better
AnythingLLM provides more than document chat. It also supports AI Agents inside a workspace. An Agent can use tools based on the task, such as browsing the web, performing specific operations, or connecting to external services. The project also offers a no-code Agent builder, MCP compatibility, scheduled tasks, and intelligent tool selection. This extends the product from answering document questions to completing work with knowledge and tools.
From an engineering perspective, the most important Agent design question is not how many tools the model can see. It is whether tool permissions, input formats, error responses, and observability are clearly designed. The AnythingLLM README says that intelligent tool selection can reduce token usage per query as the number of tools grows. This is a practical direction: the model does not need to read every tool description on every request and can first select the capabilities that are likely to be relevant.
In practice, a narrow-to-broad tool strategy is safer:
1. Start with a read-only tool, such as querying internal documents or reading a status value.
2. Define an explicit schema, timeout, retry policy, and error message for each tool.
3. Add human confirmation or a dry run before any action that changes data.
4. Record every Agent tool call, its parameters, result, and user identity.
5. Open write access or external network capabilities gradually, only after success rates and risks are acceptable.
MCP compatibility can lower the barrier to integrating tools, but being able to connect is not the same as being safe to hand over to a model. Browsers, automation, file systems, and third-party APIs should use least-privilege service accounts, with secrets stored in controlled environment variables or a secret manager rather than in prompts or documents.
Replaceability across models and the vector layer
AnythingLLM supports many LLM and embedding providers, including OpenAI, Azure OpenAI, Anthropic, AWS Bedrock, Google Gemini, Ollama, LM Studio, LocalAI, OpenRouter, Mistral, Groq, and DeepSeek. The official materials also list multiple embedding, speech, and vector-database options. This provider abstraction is useful for experimentation: a team can begin with local models to control cost and data flow, then switch to a cloud model when higher quality or lower latency is needed.
However, switching providers is not completely painless. Context windows, tool calling, vision, embedding dimensions, rate limits, and safety policies differ across models. In particular, after changing the embedding model, an old index usually cannot be assumed to remain compatible and may need to be rebuilt. When configuring providers, it is worth recording:
- The exact model and embedding-model version or identifier.
- Chunk size, overlap, vector dimensions, and distance metric.
- Retrieval top-k, reranking, and prompt templates.
- The provider's data-retention, training-use, and region settings.
Without versioning these parameters, it becomes difficult to determine later whether a quality drop was caused by changed documents, a changed model, or changed retrieval settings.
Architecture: it is really a multi-service monorepo
The official technical overview divides the project into several major areas: a Vite and React frontend, a Node.js Express server that handles interactions and vector-database or LLM operations, a collector responsible for document processing, Docker build and deployment content, and submodules such as the embed component and browser extension.
This layering explains how the project can serve both desktop users and self-hosted servers. The frontend handles workspace and chat experiences, the server centralizes application logic, and the collector isolates expensive or format-specific document processing. For contributors, understanding this boundary is more effective than tracing a vector query from the UI immediately.
The development environment can follow the README from the repository root by running yarn setup, then starting yarn dev:server, yarn dev:frontend, and yarn dev:collector separately. This approach is suitable for reading and modifying the source. If the goal is simply to use the product, Docker or a Desktop release should be preferred so the full build toolchain is not an initial burden.
Deployment choice: decide the data boundary before the platform
AnythingLLM provides Docker, Desktop, and deployment paths for AWS, GCP, DigitalOcean, Render, and other platforms. When choosing one, do not compare only startup difficulty. First answer: "Which data is allowed to leave our environment?"
For personal research or a non-sensitive prototype, Desktop can provide the fastest start. For team sharing and permission management, Docker is better suited to a service deployment. If cloud networking, backups, and monitoring standards already exist, the application can be placed in an existing VM or container platform.
A basic self-hosting checklist looks like this:
- Back up the application, data directory, and vector index separately.
- Use a reverse proxy for TLS and limit exposure of the administration interface.
- Configure an allowlist of model providers so users cannot switch to unreviewed endpoints freely.
- Set up health checks and disk-usage alerts, especially for document processing and vector-index growth.
- Assign different permissions to administrators, regular users, and Agent tools.
- Export configuration before upgrades and run regression tests with representative questions.
The official README also states that AnythingLLM includes telemetry. It collects anonymous usage information such as installation type, document events, vector-database type, LLM provider or model tags, and chat events, and provides DISABLE_TELEMETRY or in-application controls to disable it. This is a privacy boundary to review before deployment. Even with telemetry disabled, external LLMs, embedding providers, vector databases, or model CDNs may still create necessary outbound connections.
Which real-world situations fit?
Internal knowledge entry point
Organize engineering standards, product documents, customer-support manuals, and process descriptions into separate workspaces so colleagues can query them in natural language and see the sources. This is the easiest value proposition to validate because success can begin with whether the answer cites the correct passage, rather than requiring a fully autonomous Agent from day one.
Research assistant for private documents
Research and consulting work often involves material that should not be uploaded directly to a public service. Self-hosting and local-model support allow a team to control the data flow first. When using a cloud provider, the team must additionally confirm the contract, region, and provider data-processing policy.
AI application prototype
AnythingLLM's support for multiple models, vector databases, APIs, and an embeddable chat widget can shorten the path from an idea to an interactive demo. When requirements are still changing, validating the user flow with a mature application layer is often more economical than immediately building a frontend, RAG pipeline, and administration console from scratch.
Scheduled knowledge work
Scheduled tasks let an Agent execute prompts or tasks on a cron-like schedule. This is useful for daily summaries, file-change checks, or recurring reports, but it should be treated as a production job: define re-entry behavior, failure notifications, execution time limits, and output retention. The fact that a schedule can be created in a UI does not make the workflow reliable by itself.
What should not be handed over directly
AnythingLLM is a capable application layer, but it does not automatically complete every piece of platform engineering for a team. If strict cross-tenant isolation, fine-grained data lineage, complex approval flows, key rotation, centralized audit logs, service-level SLOs, or large-scale concurrency are required, the deployment may still need a gateway, identity layer, observability, and policy layer around it.
Likewise, RAG answer accuracy cannot be judged from a single demo. Document versions, scan quality, table parsing, chunk boundaries, and retrieval recall all affect results. Before adoption, prepare an evaluation set containing normal questions, cross-document questions, unanswerable questions, outdated documents, and permission-boundary cases. Run it again after changing the model, embedding, or prompt.
A pragmatic adoption sequence
If AnythingLLM is going into a team workflow, I would recommend four stages:
1. Individual validation: Use non-sensitive files to confirm parsing, citations, model switching, and the basic workspace experience.
2. Small-team pilot: Add real but classified documents, create 20 to 50 representative questions, and record accuracy, latency, and cost.
3. Permissions and operations: Move to Docker or an existing deployment platform, then add TLS, backups, monitoring, permissions, telemetry decisions, and an upgrade process.
4. Controlled Agent expansion: Begin with read-only tools and add write capabilities only with approvals, least privilege, and audit logs.
The point of this sequence is to validate data and retrieval before automation. Many AI projects begin by demonstrating what an Agent can do without first confirming that it can reliably find the right document. When the knowledge layer is unstable, adding more tools only spreads errors to more systems.
Final thought: treat it as a starting point, not the finish line
The most notable aspect of AnythingLLM is that it turns the chain of private data, models, RAG, Agents, and self-hosting into a directly usable product. For people who want to validate an AI workflow quickly, it can eliminate a large amount of glue code. For teams that care about data control, it offers local-first behavior and multiple deployment options. For developers, it is also a real monorepo that can be read layer by layer, from frontend and server to collector and connectors.
Its mature use pattern is not to open every permission at once. It is to place the product inside clear data boundaries and an evaluation process. First use workspaces and citations to establish a trustworthy knowledge entry point, then add Agent tools gradually with least privilege. First stabilize the service with Docker and backups, then consider model routing and scheduled automation.
If your need is to help a team start working with its own documents and models, AnythingLLM is worth considering. If your need is to build a fully custom, strictly compliant, large-scale AI platform, treat AnythingLLM as a reference implementation or prototype foundation and reserve engineering capacity to build the missing governance layer yourself.