LlamaIndex Is More Than RAG: A Practical Framework for Connecting Private Data to Agents
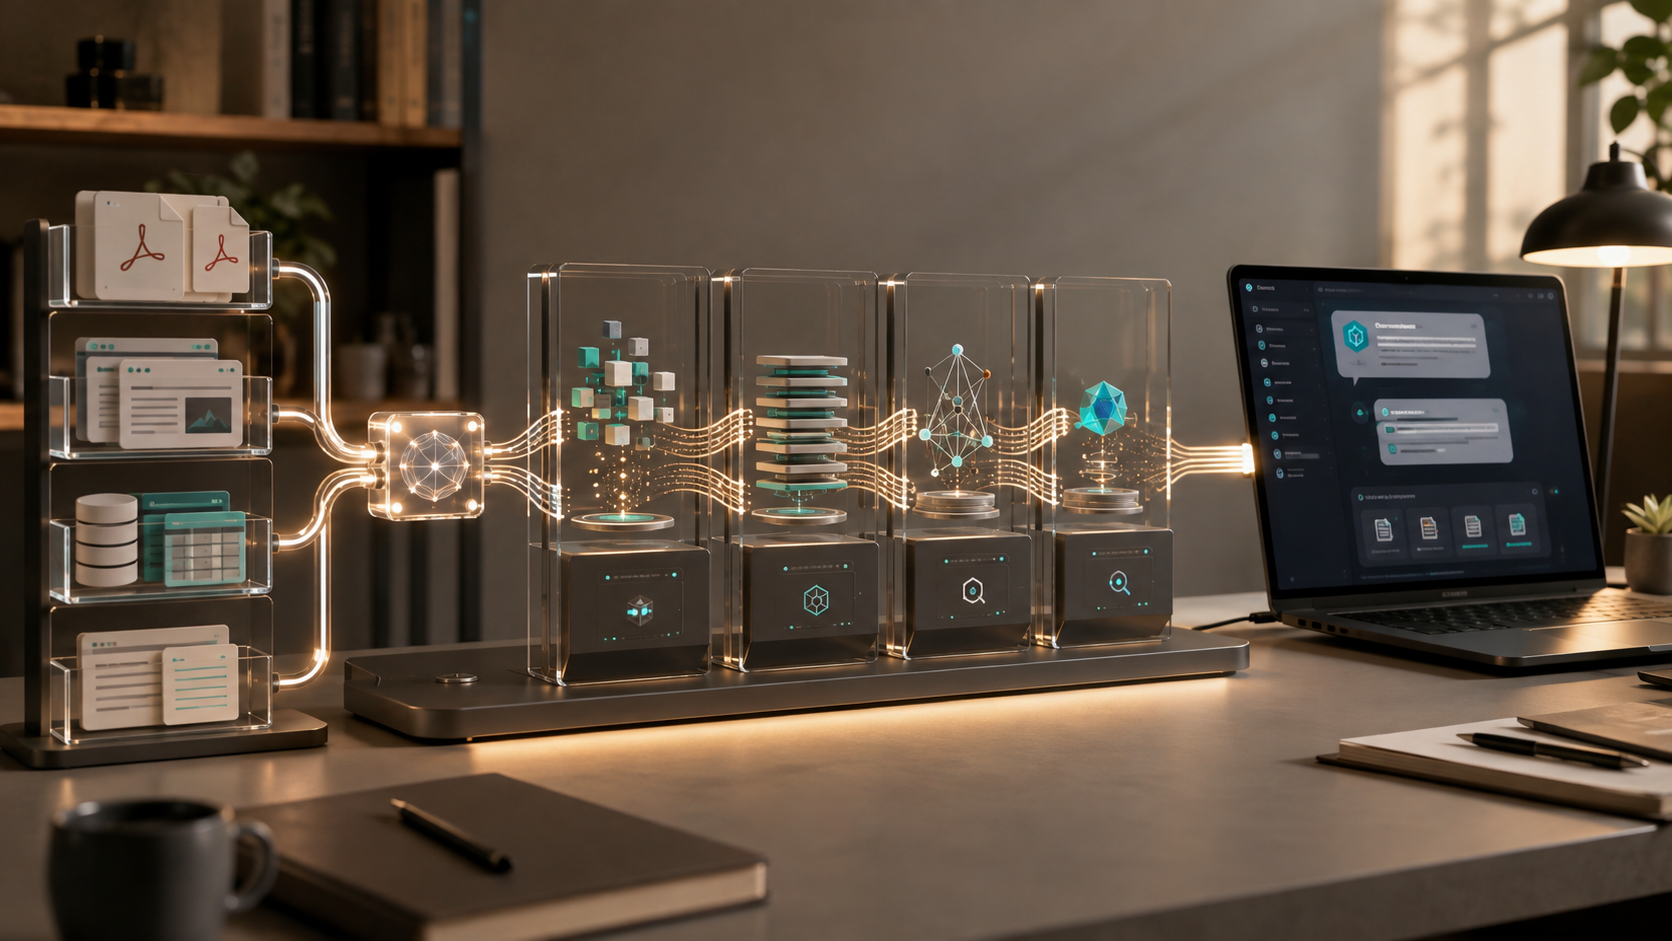
LlamaIndex Is More Than RAG: A Practical Framework for Connecting Private Data to Agents
Many teams can call an LLM quickly, yet still get stuck when the application must use company documents, product specifications, support records, or databases. The hard questions begin immediately: where should data be loaded from, how should PDF structure be preserved, how should documents be split, how should retrieved results be ranked, and when should an agent search data or call a tool?
That is why I think LlamaIndex deserves to be understood again. It is not merely a package for building RAG demos. It is a data framework between external information, LLMs, and agents. The official LlamaIndex OSS description presents it as an open source framework for building agentic applications. Its README also keeps the central data framework idea clear: connect data, organize it, retrieve relevant context, and make that context available to an application or model.
The short version: LlamaIndex is for context engineering
If the only question is how to call a model once, LlamaIndex may feel too large. If an application must continuously process private data and keep data sources, indexes, retrievers, query engines, and agent workflows replaceable and testable, it becomes much more useful.
I see three layers in its value:
1. Data access: Convert PDFs, documents, web pages, APIs, and SQL sources into Documents or Nodes that an application can process.
2. Context organization: Use chunking, metadata, indexes, embeddings, retrievers, and rerankers to decide what the model sees.
3. Reasoning and workflows: Pass retrieved context to a query engine, chat engine, agent, or workflow to create an interactive application.
This separation matters because RAG failures rarely come from the model alone. Incorrect loading, bad chunk boundaries, missing metadata, and weak retrieval are often misdiagnosed as an LLM intelligence problem. LlamaIndex gives these stages clearer programming boundaries.
Why the architecture can scale
The LlamaIndex Python packages use a core plus integrations model. llama-index-core provides central abstractions, while an application selects packages for its LLM, embedding model, vector store, data loader, and other integrations. The official README mentions more than 300 integration packages. The point is not to install everything; it is to decouple providers from the core flow.
A core application can use general LLM and retriever interfaces while the implementation is changed to another model provider or vector database. This makes it possible to move quickly during prototyping and later change components for cost, latency, data isolation, or deployment requirements.
The abstraction is not free. When retrieval quality is poor, the team must know which integration, embedding model, index, and persistence path are actually in use. Calling only high-level APIs without understanding the data path still makes debugging difficult.
Build one verifiable document question-answering flow first
I would not start with a multi-agent system. First build the smallest document question-answering flow that can be verified. Confirm that the data can actually be found before adding more behavior:
from llama_index.core import VectorStoreIndex, SimpleDirectoryReader
documents = SimpleDirectoryReader("./data").load_data()
index = VectorStoreIndex.from_documents(documents)
query_engine = index.as_query_engine()
response = query_engine.query("What is the main conclusion of this document?")
print(response)
The code is short, but a production system is not only these lines. During the first verification I would check three things:
- Whether files in
./datawere really loaded instead of producing an empty index after a silent failure. - Whether the answer can be found in the source document, rather than being confused with the model's general knowledge.
- Whether an updated document requires a rebuild, an incremental update, or removal of an older version.
For a clean local environment, create a project with uv init and add the package with uv add llama-index. Put one or two public test documents in data, run the program, and verify the four steps of loading, indexing, querying, and output. This checkpoint is more valuable than connecting ten sources immediately because it separates environment problems from retrieval problems.
Separate data sources from model providers
Once the project becomes a team application, I would not put every setting in one Python file. At minimum, separate data loading, model configuration, index construction, and the query interface:
app/
  settings.py       # model, embedding, and environment settings
  ingest.py         # loading and chunking
  index.py          # index construction and persistence
  query.py          # query engine or agent
  evaluation.py     # test questions and retrieval evaluation
data/
The reason is practical. Changing a model provider should not require rewriting data ingestion. Moving from local storage to a remote vector database should not affect the front-end question-answering interface. The separation between LlamaIndex core and integrations supports these boundaries.
Persistence is another important concern. A prototype can rebuild an index on every start, but a production service normally needs to save the index and record the data version, embedding model version, chunking parameters, and build time. Otherwise, when an answer changes, it is difficult to tell whether the cause was a source update, an index update, or a model configuration change.
Give retrieval to an agent only after it is stable
After document question answering is stable, it makes sense to expose it as an agent tool. The value of an agent is not giving a more fashionable name to search. It is letting the system choose tools, perform multiple steps, and return to an indexed data source when needed.
These three layers should remain distinct:
- Retriever: Finds potentially relevant data.
- Query Engine or Chat Engine: Combines a query and context into a response.
- Agent: Decides what to do next, such as querying a document, calling an API, or running another tool.
If all three become one black box, failures are hard to locate. My approach is to create a fixed question set for the retriever first, test whether the right context is recalled, then test whether the query engine stays faithful to that context, and only then test the agent's tool selection and multi-step behavior.
LlamaIndex Workflow is also worth attention. For multi-step, event-driven, or rerunnable agent processes, a workflow is easier to observe and test than a giant prompt containing all the logic. The steps for receiving a question, querying data, organizing context, generating an answer, and checking the result can have explicit inputs and outputs. This adds code, but improves maintainability.
Document processing is central, not an optional detail
Many RAG examples use plain text, making retrieval look easy. Enterprise data may contain tables, headers and footers, scanned images, fields, attachments, and version markers. If parsing loses structure at the beginning, better embeddings and generation cannot fully recover it.
The LlamaIndex ecosystem also lists LlamaParse and document-agent capabilities in the official README. These services can support more complex parsing, structured extraction, and indexing, but they are separate cloud offerings and should not be confused with the open source core. Before adoption, confirm whether data may leave the private network, how API keys are managed, how costs are estimated, and whether a self-hosted parsing path is required.
I would start with a data quality checklist: Is every document complete? Is its encoding correct? Are tables readable? Are page numbers and source metadata preserved? Can different versions of the same document be identified? These checks are closer to the root cause of RAG quality than prompt tuning.
Limits: LlamaIndex does not guarantee correct answers
The first limit is retrieval quality. A framework can provide components, but it cannot choose the best chunk size, top k, metadata schema, embedding model, or reranking strategy for a particular corpus. Those choices require evaluation with real questions.
The second limit is cost and latency. Parsing, embedding, vector search, reranking, and LLM generation can each add cost or delay. A multi-step agent adds more tool calls. If acceptance is based only on whether an answer sounds reasonable, peak traffic and long documents can produce unpleasant surprises.
The third limit is debugging overhead from the abstraction layer. When many packages and integrations are involved, compatibility, API changes, and failures in external services must be observed. Production systems should pin dependencies, record retrieval sources and latency, and provide traces that make failures reproducible.
The fourth limit is security. Any agent that can read private data or call tools must address permissions, data scope, prompt injection, sensitive information leakage, and tool abuse. A framework interface is not a reason to give a model every document and operation permission at once.
How I would evaluate a LlamaIndex project
For me, the important question is not whether a demo can run in five lines. I would ask these five questions:
1. Can the data be represented correctly? Are source, version, permission, and metadata preserved?
2. Can retrieval be measured? Is there a realistic question set for recall, ranking, and citation accuracy?
3. Can components be replaced? Are the LLM, embedding model, vector store, and parser clearly separated?
4. Can the process be observed? Can the team see why an agent chose a tool, which context it used, and how much time and cost it consumed?
5. Are failures controlled? Does the system degrade safely when data is missing, a model times out, an external API fails, or permission is denied?
If these questions have no clear answers, I would not move a polished demo directly into production.
Who should try it first?
I would recommend LlamaIndex to teams with a document question-answering or knowledge-base use case, teams building LLM applications in Python, teams that must connect several data sources, and teams expecting to expand from simple RAG to tool use and agent workflows.
If the requirement is only one-off summarization or fixed-template generation, or if the team cannot maintain a data pipeline and evaluation set, a full framework may add unnecessary complexity. A lightweight API call combined with explicit data processing may be easier to maintain.
Conclusion: build the data flow before the agent
My view is that LlamaIndex is most valuable not as a wrapper for a chat window, but as a set of composable data and reasoning components that bring private information into LLM applications in a more orderly way.
The practical adoption sequence is to validate loading and retrieval with a small document set, separate model, embedding, index, and storage boundaries, establish an evaluation question set, and only then add agents and workflows. This path is less flashy than building a fully autonomous agent in a day, but it is more likely to produce a system that is maintainable, observable, and governable.
If you are building an enterprise knowledge base, a document agent, or an AI application that needs private-data context, LlamaIndex belongs on the shortlist. Treat it as infrastructure for context engineering, not as a guarantee of correct answers.
References