MiroFish Is Not an Oracle: A Multi-Agent Simulation as an Inspectable Decision Sandbox
MiroFish Is Not an Oracle: A Multi-Agent Simulation as an Inspectable Decision Sandbox
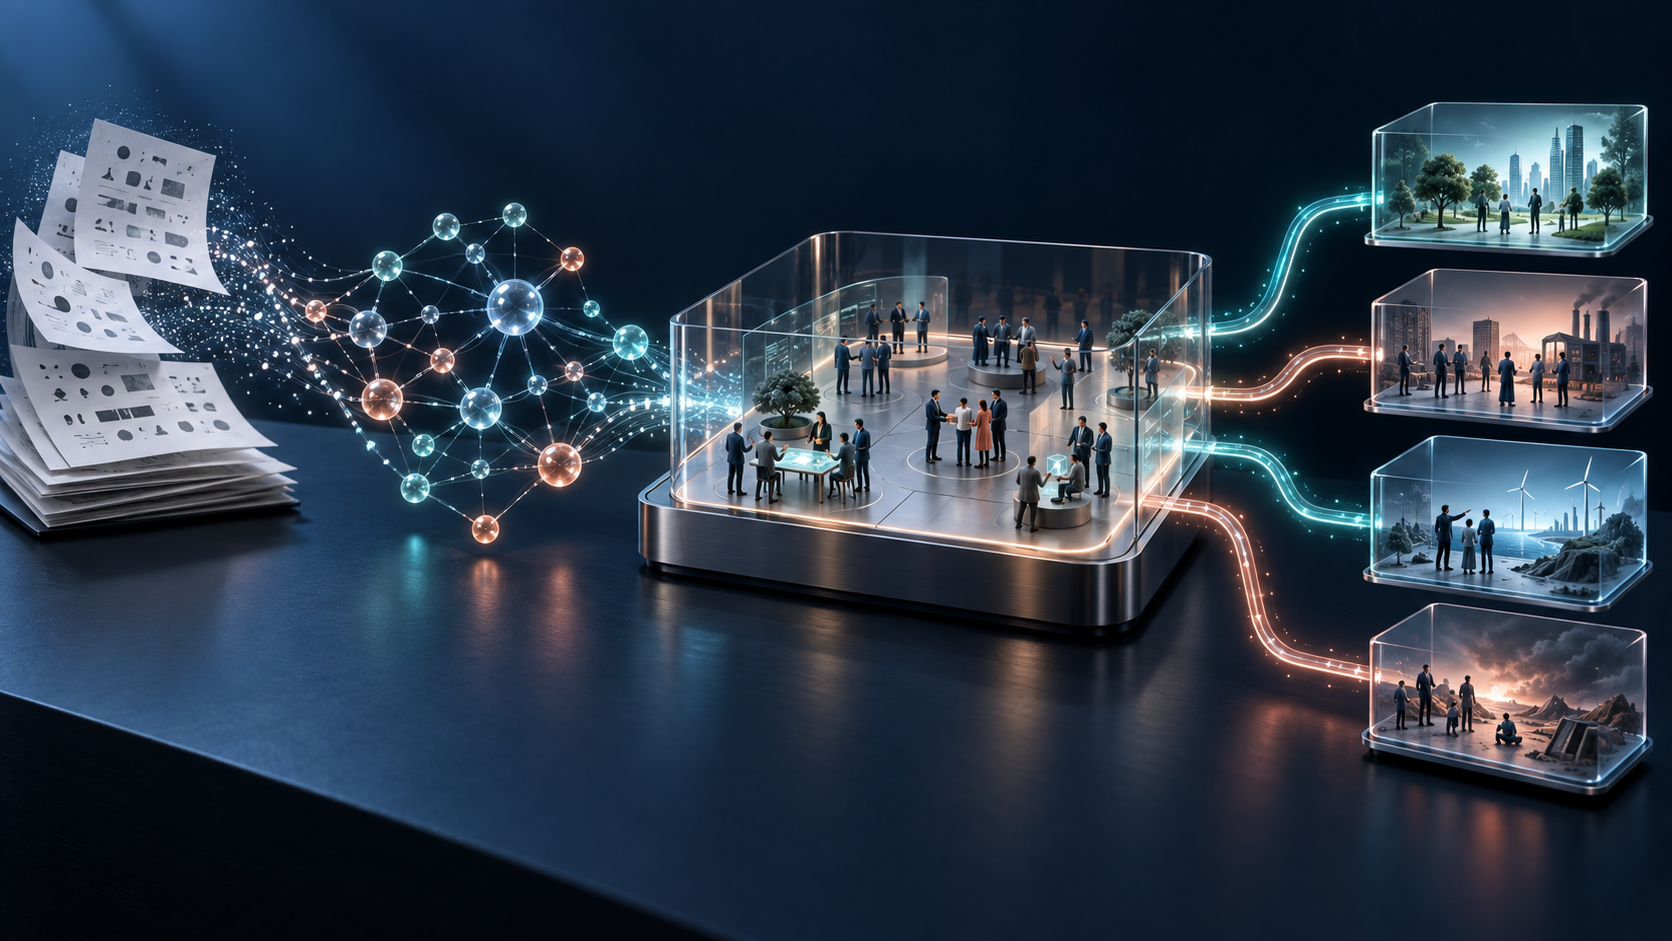
When a team needs to estimate how a policy, product launch, or public-opinion event might unfold, the usual options are to consult experts, run a survey, or build a model from historical data. MiroFish offers another path: turn a set of real-world materials into a knowledge graph, generate AI agents with different profiles, let them interact in a simulated social environment, and then assemble possible scenarios into a report.
That idea is compelling—especially when we want to ask, “How might the discussion change if one condition changed?” But I think the best way to understand MiroFish is not as a system that can see the future. It is more usefully treated as a multi-agent decision sandbox where we can adjust assumptions, observe interactions, and compare scenarios. It can broaden a discussion; it cannot certify what will happen in the real world.
First, distinguish a simulation from a forecast
MiroFish’s README positions it as a prediction engine and lists news, policy drafts, and financial signals as possible inputs. In the documented workflow, the system extracts people and relationships from the source material, builds a graph, generates agent profiles, runs those agents in Twitter- or Reddit-like environments, and produces a report through ReportAgent. After the simulation, users can also interact with the agents or the report agent.
The process is best suited to answering a narrower question: “Given these inputs, these profile definitions, and these interaction rules, what discussion paths might emerge?” A large number of agents does not automatically make the run a representative survey of real people. Nor does a complete-looking report prove that a particular scenario will occur.
That is the key distinction between simulation and prediction. A reliable forecast normally needs evaluation data, baselines, error measures, and a record of repeated validation across events. In the MiroFish README, quick-start material, and code entry points I reviewed, I did not find a reproducible benchmark for forecast accuracy. Until such validation is available, treat simulation output as a hypothesis to investigate—not a decision-ready conclusion.
MiroFish’s workflow in four parts
1. Build a graph from source material
The user supplies seed material and a question to explore. MiroFish’s graph service sends text to Zep Cloud to create nodes and relationships; the code’s GraphBuilderService explicitly uses the Zep API to build a standalone graph. This gives later agent generation a background context to retrieve, rather than starting from a single prompt with no structured source.
The quality of the material affects everything that follows. If the source represents only one viewpoint, leaves out important actors, or treats unverified claims as facts, the graph and the generated profiles can carry those biases into the simulation. A graph is not a fact-checker: it organizes the supplied material; it does not automatically establish whether that material is reliable.
2. Generate simulation settings and agent profiles
MiroFish then uses the simulation requirements, document text, and graph entities to generate time settings, event settings, and a batch of agent profiles. The official code handles these settings in separate stages and generates agent configurations in batches. Each profile’s background and behavior are part of the simulation’s initial conditions.
This means results depend on more than the number of agents. They also depend on which roles the system extracts, how those roles are described, and how the model turns those descriptions into actions. If an important viewpoint is absent from the source material, adding more agents will not magically create a representative sample of the real population.
3. Run interactions in the OASIS social environment
MiroFish uses CAMEL-AI’s OASIS as its simulation engine. OASIS is an open-source social-interaction simulator; its README describes Twitter- and Reddit-style environments and actions such as following, commenting, and reposting. MiroFish’s runner can select Twitter, Reddit, or parallel execution. Graph-memory updates are a separate option, and the default in the runner code is off.
These mechanics make the system more structured than a one-shot chat: agents take actions under platform and event rules, the run records interactions, and the resulting activity becomes input to reporting and exploration. One important caveat: scale figures in the upstream OASIS README describe that engine’s stated capability. They are not a guarantee that MiroFish will reach the same scale on every machine, model, or configuration.
4. Generate a report, then explore the run
After a simulation, ReportAgent assembles a report from the simulated environment. Users can also ask follow-up questions of the report agent or individual agents. This is useful for questions such as “Why did this scenario emerge?” or “How might this role respond to different information?”
Still, follow-up answers come from the same synthetic environment. They can help explain what happened inside the run, but they are not testimony from real interviewees and should not replace external verification.
Where it may be useful
I would start with using MiroFish to generate scenarios worth checking, rather than to make the final decision. A communications team could use verified event material to explore discussion paths under different response strategies. A product team could compare two launch messages and identify possible sources of user confusion. Researchers or writers could use defined roles and background material to explore plausible storylines or social interactions.
A good first question has a clear scope, a variable that can be changed, and outcomes that can be checked elsewhere. “If we delay the announcement by a week, which stakeholders might change their position?” is a better starting point than “Predict what will happen to this company.” The first question can be broken into comparable conditions. The second is so broad that a detailed answer may sound useful while remaining difficult to evaluate.
Getting started: begin with a small scenario
MiroFish’s official quick start offers source-code and Docker deployments. The source-code path requires Node.js 18 or later, Python 3.11 through 3.12, and uv. The system also needs an LLM API compatible with the OpenAI SDK format and a Zep Cloud account. The example environment lists LLM_API_KEY, LLM_BASE_URL, LLM_MODEL_NAME, and ZEP_API_KEY. Keep the actual credentials in your local .env file; do not paste them into source code, issues, or public logs.
git clone https://github.com/666ghj/MiroFish.git
cd MiroFish
cp .env.example .env
Edit the local .env file with the required model-service and Zep Cloud settings. Then install the frontend and backend dependencies and start the services:
npm run setup:all
npm run dev
According to the README, the frontend defaults to http://localhost:3000 and the backend API to http://localhost:5001. If startup fails, first check the Node.js, Python, and uv versions. Then confirm that .env is complete, the LLM_BASE_URL is reachable, and the Zep Cloud credentials are valid. Avoid starting with a large document set or many simulation rounds. The project README warns that runs can be costly and recommends beginning with fewer than 40 rounds. That is the project’s own usage guidance, not a universal cost estimate across models, source materials, and scenarios.
For a first run, I would use one short, verifiable source document, write down one concrete question, keep the agent scale and other settings fixed, and change only one condition. Record the source material, model name, number of rounds, profile settings, and output so that a later reviewer can tell whether the run actually produced a comparable difference. If the prompt, agent count, and event settings all change at once, it becomes difficult to tell which variable drove the result.
Turn a run into a reviewable experiment
Suppose I want to explore reactions to an announcement. I would not simply ask, “What will everyone think?” and treat the generated report as an answer. I would frame a decision question such as: “Would publishing the full timeline first, or publishing the principles first, be more likely to cause confusion about delivery dates?” I would prepare the same background material, verify that the key roles and events are represented, and make the two announcement approaches the scenario difference.
Change one major condition at a time. Keep the baseline and the alternative as similar as possible in their source material, agent scale, number of rounds, and model settings. Save the document version, question, configuration, run time, and output for each run. If repeated runs with the same settings produce different paths, preserve that variation instead of selecting only the result that best supports the expected answer. Those records help a team check whether a conclusion came from an input or setting—or merely from a persuasive narrative.
When reading the report, separate three things: actions that occurred inside the simulation, the agent or report agent’s explanation of those actions, and the real-world hypothesis the team draws from them. They are not the same kind of evidence. Select the most important hypotheses and check them against past events, user interviews, expert review, or a small real-world experiment. If external evidence does not support the simulation, revise the hypothesis rather than defending the output at all costs.
This method does not turn a simulation into a calibrated forecasting model. It does make the run bounded, documented, and open to being disproved. For a team, that is often more useful than chasing a polished-looking “answer about the future.”
Limitations to account for before adoption
Agents are not a demographic sample. The profiles are generated from source material and a model; they are not a random sample of actual users. Research into public opinion or market response still needs to be cross-checked against real surveys, customer-service data, or other external evidence.
The source material creates an anchor. The graph and profiles are based on the seed material, so choices, omissions, and wording can steer the run. Before starting, note the source and time range, unverified claims, and viewpoints intentionally included.
Cost and data boundaries need attention. The workflow depends on an external LLM API and Zep Cloud. Model calls, agent count, interaction rounds, and report length can all affect usage. Running the frontend or backend yourself does not mean the full data path is offline. Check whether sensitive material may be sent to external services, and estimate API costs and data-retention implications before a pilot.
Check the license against your deployment. GitHub metadata lists the project under AGPL-3.0. If you plan to modify the code, offer it as a network service, or include it in a commercial product, read the full project license and confirm the obligations that apply. “Open source” does not mean “without conditions.”
I would not use MiroFish as the direct basis for investment, medical, public-policy, or other high-stakes decisions, and I would not present a simulation report as a public-opinion forecast. A more responsible role is as a hypothesis generator: let it suggest scenarios, then return to data, experts, and real-world validation before deciding what deserves action.
Conclusion: treat it as a simulation room, not a crystal ball
MiroFish’s strength is connecting knowledge graphs, agent profiles, social interaction, and report exploration into an operable workflow. For teams that need to expand a “what if?” discussion quickly, it offers more structure than a single chat and leaves a simulation trail that can be questioned.
But a detailed simulation does not automatically become evidence about the real world. Put MiroFish in the role of proposing hypotheses, comparing scenarios, and identifying what to investigate next, and it is worth a small pilot. Expect it to tell you what the future will be, and you are asking more than the public evidence currently supports. Treat MiroFish as a simulation room, not a crystal ball—that is the more reliable way to use it.
References