RAG Does Not Always Need a Vector Database: How PageIndex Lets Models Navigate a Document Tree
RAG Does Not Always Need a Vector Database: How PageIndex Lets Models Navigate a Document Tree
I think the most overlooked question in a RAG system is not whether the model is large enough, but how it actually finds the relevant passage. The common approach splits documents into fixed size chunks, creates an embedding for each chunk, and retrieves text through vector similarity. This path is mature and useful for large collections of short text. But when the data consists of annual reports, regulations, technical manuals, or research papers, fixed chunking can break the context that makes a passage meaningful.
PageIndex is an open source document indexing and reasoning based RAG project from VectifyAI. Its central idea is not to build a faster vector search. Instead, it converts a document into a hierarchical tree index and lets an LLM reason through chapters and subsections as a person would read a long document. This is an interesting direction, but it should not be reduced to the claim that vector databases are obsolete. The official README presents PageIndex as a vectorless, reasoning based RAG engine, and whether it fits still depends on document structure, query patterns, model cost, and acceptable latency.
The short version: relevance is not the same as similarity
The strength of vector RAG is efficiency at scale. Once documents are converted into vectors, a query can quickly retrieve semantically similar passages. For FAQs, support records, product descriptions, and many short documents, this is a practical baseline. Similarity, however, answers whether a passage resembles the question. It does not always answer whether that passage is the right evidence in the context of the whole document.
Imagine asking an annual report, “What was the operating margin in a given year, and how did management explain it?” The answer may be distributed across a financial table, footnotes, and management discussion. A single chunk may contain a similar number, but without the section relationship, table heading, or surrounding explanation, the model can produce an answer that sounds plausible while remaining incomplete.
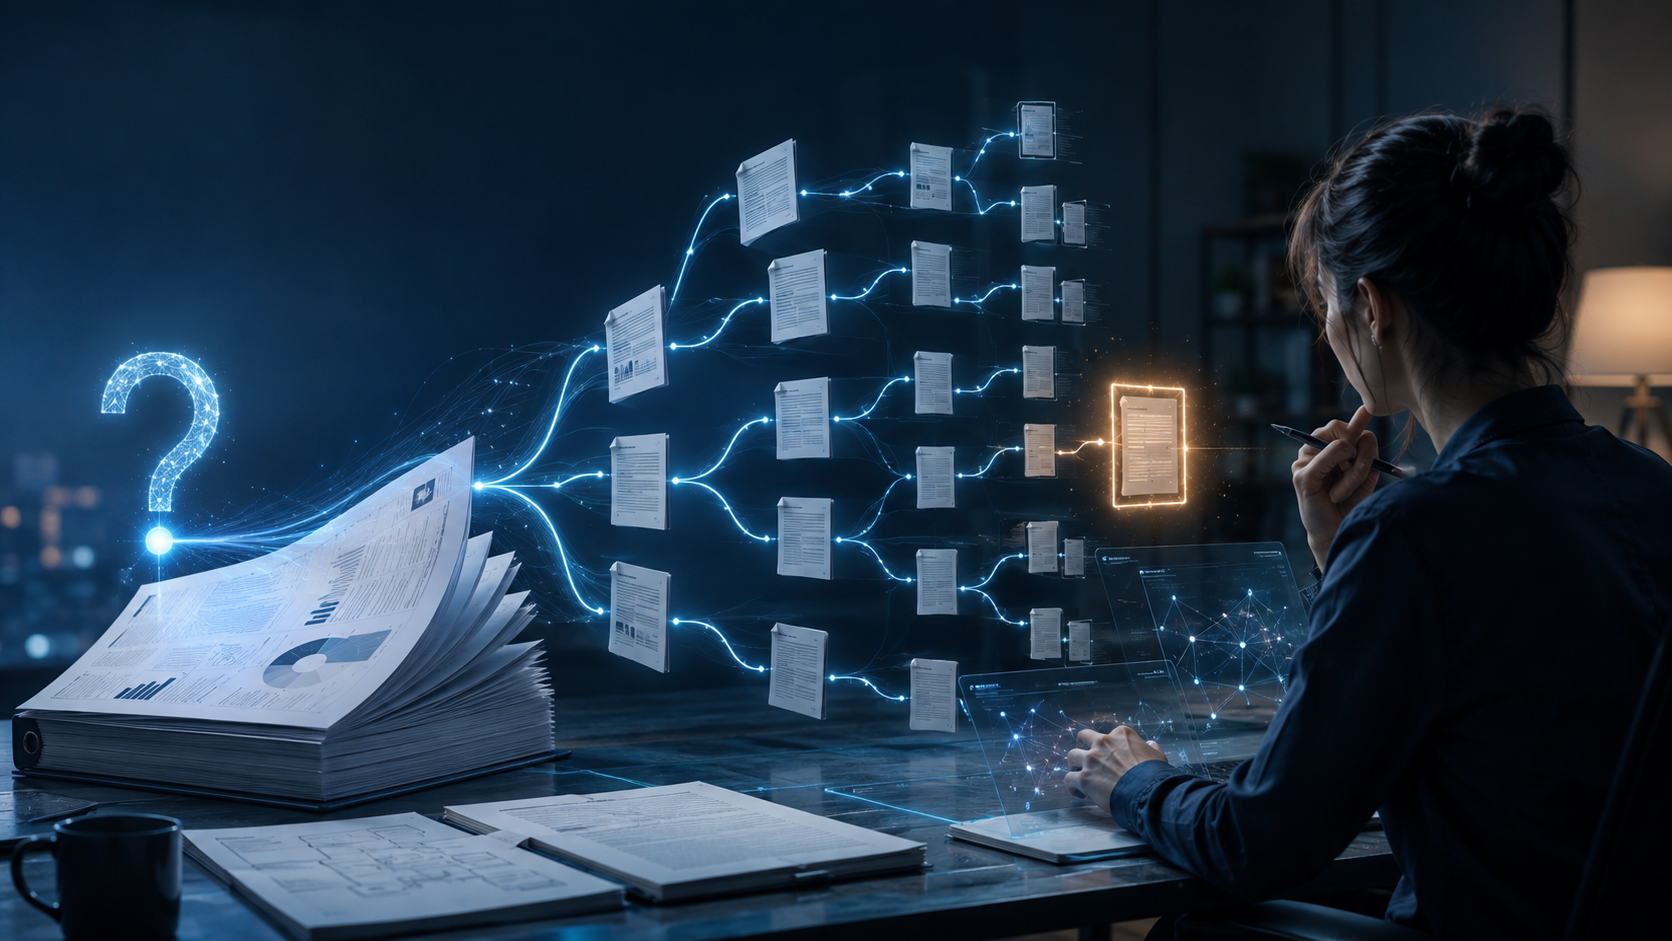
PageIndex first builds a hierarchy and then lets the model search that structure. The official description separates the process into two stages. Index generates a tree structure index from a document. Retrieve lets an agent search that tree with LLM reasoning. The retrieval unit is therefore not an arbitrary piece of text, but a section, node, or page range with a place in the document.
I think of this as turning a document table of contents into a navigable reasoning map. The model does not only ask which passage is most similar. It first determines which branch is likely to contain the answer, narrows the search, and returns to a traceable page or node. That is why PageIndex emphasizes traceable and explainable retrieval.
How PageIndex differs from ordinary RAG
1. Index: build a hierarchical document tree first
PageIndex does not simply send the entire document to a chat model. It analyzes layout and structure and creates a tree that represents relationships between sections. For PDFs with a useful table of contents, headings, page numbers, and nested sections, this can preserve the context of where information lives.
The difference from fixed chunking is practical. Chunking requires choices about chunk size, overlap, separators, and metadata. Chunks that are too small split an answer; chunks that are too large reduce retrieval precision and increase context cost. PageIndex describes itself as no vector DB and no chunking. That does not mean there is no data transformation. It means that preprocessing focuses on building a navigable document structure instead of producing embeddable fragments.
2. Retrieve: reason through the tree
When a query arrives, the model chooses potentially relevant branches, reads nodes step by step, and connects the result back to a concrete location in the document. For questions that cross sections or require context, this agentic search can be more natural than taking only the nearest chunks.
There is an engineering tradeoff. Reasoning based retrieval generally requires more model calls, so its latency is not automatically lower than vector search. PageIndex does not need to promise that every query is faster. Its value is moving the retrieval decision closer to the way a person reads a long document. Teams should measure answer quality, citation traceability, cost per query, and P95 latency rather than judging a single demo.
3. Chat: expose retrieval through a question answering client
The SDK wraps indexing and querying in a client. The README quickstart shows how to create a PageIndexClient, submit report.pdf, obtain a doc_id, and ask a question with client.chat. This makes PageIndex more than an offline indexing utility; it provides an entry point from document submission to conversational queries.
The documentation also describes streaming, multi document search, citations, and integration with the OpenAI Agents SDK, the Claude Agent SDK, or other agent frameworks. For a team that already has an agent platform, PageIndex can be treated as a pluggable document reasoning tool rather than a reason to rewrite the entire application.
How to start: validate one document before indexing a whole knowledge base
I would treat PageIndex as a retrieval strategy to validate, not as something to install and immediately use to replace an existing RAG system. The smallest official quickstart can be organized into a few steps.
Step one: prepare a Python environment and model access
The official README uses the PyPI package as the entry point:
pip install -U pageindexYou then need access to an LLM provider and must select models for indexing and querying. The index model builds or refines the tree structure. The chat model understands the question, searches the tree, and produces an answer. The official guidance suggests that a basic model can be sufficient for indexing, while the query model should be as capable as the budget permits because it directly affects reasoning based retrieval quality.
The important idea is to separate the two cost profiles. Indexing is often a one time or low frequency operation, while queries may run thousands of times a day. Using the strongest model only where reasoning affects online retrieval can be easier to budget than using the same expensive model for every step.
Step two: create a client and submit one PDF
The following is a conceptual version of the official quickstart. Use the current documentation for exact model names and provider settings:
import os
from pageindex import PageIndexClient
os.environ["OPENAI_API_KEY"] = "your-openai-key"
client = PageIndexClient(
    index="index-model",
    chat="chat-model",
)
doc_id = client.submit_document("report.pdf")["doc_id"]
answer = client.chat("What was the 2023 operating margin?", doc_id=doc_id)
print(answer)
In production, do not hardcode a real key in source code or commits. Use environment variables, a secret manager, or the secret store provided by the deployment platform. After submission, confirm that a valid doc_id is returned and ask a question that can be checked against the original PDF. The first test should not be completely open ended. Use a number, date, clause, or section whose answer can be verified by a person.
Step three: build a small evaluation set
Do not draw a conclusion from one question. I would select ten to twenty questions from the target document and divide them into three groups: questions answerable from one section, questions requiring connections across sections, and questions designed to distinguish similar but irrelevant passages. For every question, record the expected answer, correct page, citation requirement, response time, and model usage.
Run the same set through the existing vector RAG and PageIndex. At minimum, compare:
- The rate of finding the correct evidence, not only text similarity.
- Whether the answer preserves necessary conditions and context.
- Whether citations lead back to the correct page or node.
- Initial indexing cost, query tokens, and query latency.
- Whether rebuilding the index after a document update is simple and safe for production.
This evaluation is closer to a real adoption decision than a single benchmark number. Enterprise documents differ in layout, language, tables, and permission rules.
Why long professional documents are the right test case
PageIndex has a clear target: financial reports, legal documents, regulatory filings, technical manuals, medical literature, academic textbooks, and other long professional documents are where it has the greatest chance to show a difference. These documents often contain a usable hierarchy, and the same term can play different roles in different sections.
For a regulation, the question may not be which paragraph mentions a word. It may be which exception applies under a particular condition. For a technical manual, the meaning of a parameter may depend on the version, platform, and prerequisites. If a system retrieves only similar passages, the model must infer the relationship between them. If the index preserves the table of contents and node hierarchy, the model has an additional path for reasoning.
A document having structure does not mean that the structure is correct. Poor scans, missing tables of contents, table parsing errors, cross page columns, and image heavy pages can all make a tree unreliable. Before adoption, sample and inspect the generated tree. Do not equate having a tree with understanding the document.
Costs, limitations, and common misreadings
It is not a replacement for every RAG system
For short text, high query volume, millisecond response requirements, or data with no stable hierarchy, a vector index may remain the more direct choice. PageIndex’s reasoning search uses model calls, so query cost and latency belong in the design. A hybrid architecture may be more sensible: use metadata or keyword filtering for a coarse pass, then apply tree reasoning to a small set of long documents instead of sending every query through the same path.
Indexing is not free
The official README provides local indexing cost and time estimates and warns users to read the documentation and start small. Even if one indexing run is affordable, a production estimate should include document update frequency, rebuild strategy, model price changes, retries, and storage. Frequently changing data can give a different total cost from a conventional embedding pipeline if every update rebuilds a complete tree.
Reasoning is not the same as factual accuracy
PageIndex emphasizes reasoning based retrieval, but a model can still follow the wrong branch and hallucinate or cite the wrong evidence. Traceability helps review; it does not replace data governance, permissions, version management, or human sampling. In finance, legal, and medical use cases, require sources and design refusal and human review paths.
Pin versions and test the API
Open source SDKs evolve. The current README describes local mode, Cloud, PageIndex Flash, multi document features, and agent integrations as capabilities that can change with releases. Treat the installation command as a starting point. Pin the package version, read the documentation for that version, and validate index output and query results in CI. Do not assume that the latest package behaves exactly like an older quickstart.
Set privacy and data boundaries first
If documents contain personal information, trade secrets, or regulated data, first determine which content is sent to which model provider. Local mode can run indexing, retrieval, and chat on a machine, but local execution does not mean every model is local. If an external LLM API is used, review data transfer, retention, and provider terms again. This question is more fundamental than choosing vectors or trees.
How I would decide whether to adopt it
My order of evaluation starts with the documents and then moves to the technology. If the data consists of short statements, standard questions, and clear metadata, improving conventional vector RAG is often the better investment. If the data consists of hundreds of pages of professional material, the questions require cross section understanding, and the team cares about citations that lead to original locations, PageIndex deserves an A B test.
The second question is the cost of an error. If a mistake only makes someone search one more time, extra reasoning cost may be a good trade for a better experience. If a mistake affects a contract, financial decision, or medical action, a demo success rate is not enough. Add citation checks, access control, approvals, and a fallback path.
The third question is whether the team can maintain an evaluation process. Without a fixed question set, version records, and cost monitoring, changing any RAG component becomes guesswork. PageIndex should prove its value under the same data, questions, and model conditions as the existing system. The phrase no vector database is interesting, but it is not an adoption plan.
Conclusion: turn retrieval from a similarity problem into a reading problem
PageIndex offers a useful hypothesis: the bottleneck in long document question answering may not be a weak embedding model. It may be that the system discarded the document’s original structure. A hierarchical tree combined with LLM reasoning makes retrieval more like finding a chapter from a table of contents and then returning to a page to verify it. That design is especially promising for structured, long, professional documents that require context and source tracking.
My recommendation is not to discard vector RAG across the board. Put PageIndex in the right position: select a small set of high value long documents, create a verifiable evaluation set, and compare answer quality, citations, cost, latency, and maintenance. If tree reasoning reduces important errors, expand it through a hybrid architecture. If the document structure is unstable or query volume is very high, the conventional approach may still be the better engineering choice.
References