Google LangExtract: Ground LLM Extractions in Source Text for Verifiable Unstructured Data
Google LangExtract: Ground LLM Extractions in Source Text for Verifiable Unstructured Data
Many LLM demos follow the same pattern: send a document to a model and ask for JSON. Production problems appear later. Which sentence supports a field? Did the model copy text from a few-shot example instead of the input? What happens to cross-paragraph relationships after a long document is split into chunks? If a reader cannot return to the source and verify an extraction, a polished JSON response is still difficult to trust.
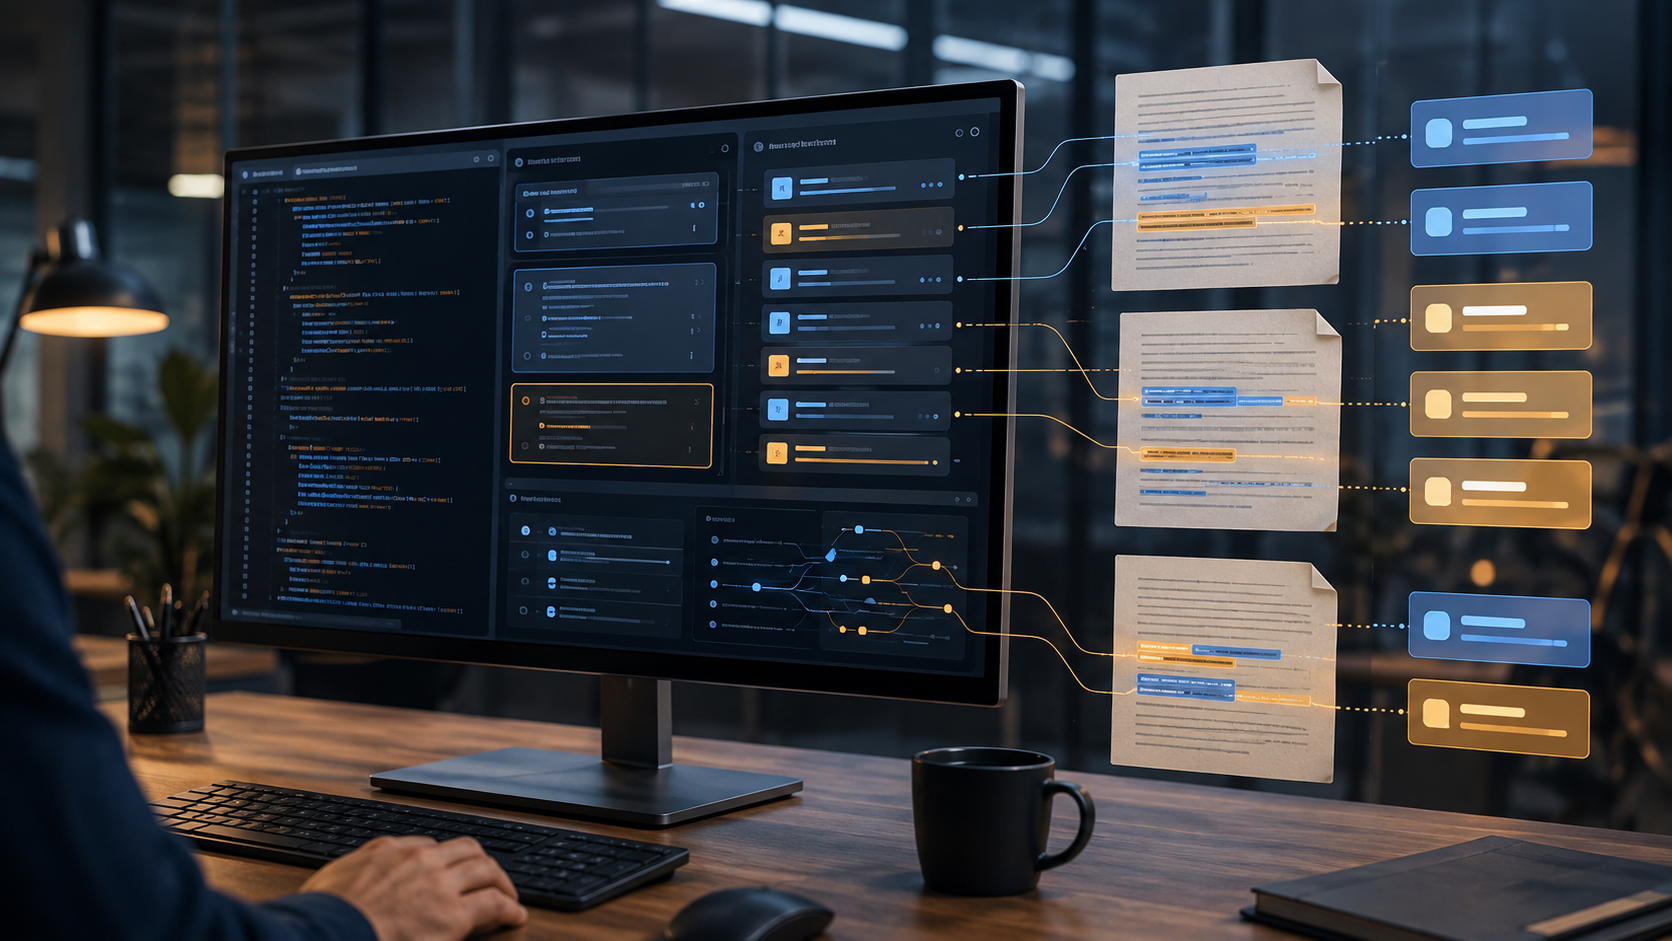
In this GitHub scouting run, I selected Google's langextract. At the time of review it had more than 38,000 stars and was still receiving updates. It is an Apache 2.0 Python library, not a prompt collection or learning list. Its central idea is straightforward: use an LLM to extract structured information from unstructured documents, map every extraction back to an exact character span in the source, and produce an interactive HTML view for review.
That makes LangExtract more than an LLM that emits JSON. It puts extracted data, source evidence, and human review into one workflow. My conclusion is that teams handling long documents, clinical notes, customer conversations, legal text, or research material should care less about whether a model can produce fields and more about whether every field keeps auditable evidence.
The short version: LangExtract solves traceability, not hallucinations
LangExtract has four distinctive layers:
1. Define an extraction task with natural-language instructions and few-shot examples. No fine-tuning is required for the basic workflow.
2. Chunk long documents and run inference in parallel. Multiple extraction passes can trade additional cost for higher recall.
3. Align model output back to the source text. Each extraction can carry a char_interval, an alignment_status, and structured attributes.
4. Connect JSONL output to an interactive visualization. Reviewers can inspect thousands of extractions in their original context instead of reading a flat table.
The combination is the important part. A schema constrains the shape of a response, but it does not prove that a field has evidence. LangExtract treats the shape of the data and its location in the source as related concerns.
There is also an important boundary. Source grounding answers whether an extracted span can be found in the input. It does not prove that an inferred attribute is true. The README notes that quality still depends on the model, prompt, examples, and task complexity. In medical, legal, or financial systems, LangExtract is a foundation for reviewability, not an automatic approval system.
Why its data model is more useful than a JSON dictionary
A LangExtract Extraction can contain extraction_class, extraction_text, char_interval, alignment_status, extraction_index, group_index, description, and attributes. The most important field is char_interval: it represents the start and end positions of an extraction in the source text, with an inclusive start and an exclusive end.
That design gives a production pipeline three practical benefits:
- Evidence can be reopened. A frontend does not need to guess which sentence supports a field; it can highlight the character range directly.
- Unaligned output can be separated. If a model copies text from a few-shot example and that text is not present in the real input, the system may not be able to locate it and
char_intervalbecomesNone. That is safer than silently inserting the result into a database. - Relationships and attributes remain available. A medication can be extracted with dosage, route, and frequency attributes, or a person and a relationship can be stored without reparsing a paragraph later.
This is why I see LangExtract as a good fit for human-in-the-loop data preparation. The model proposes candidates, the system preserves evidence, and a person verifies the highlighted span. It does not remove review; it reduces review from rereading an entire document to checking the relevant passages.
From prompt to visualization: the complete extraction pipeline
1. Examples define behavior
Examples are not decoration. They demonstrate extraction classes, source spans, and attributes. The official documentation asks that extraction_text appear verbatim in the example text whenever possible, without overlap, and in order of appearance. Misaligned examples produce prompt alignment warnings.
The strictness is useful. If the example already breaks the relationship between evidence and structured data, the model has no reliable pattern to follow. LangExtract moves part of the data-annotation contract into prompt design.
2. Long documents are chunked before inference
The official examples expose options such as max_char_buffer, max_workers, and extraction_passes. Chunking controls the amount of context sent to each inference call. Parallel processing improves throughput. Multiple passes spend more compute to search for additional entities.
In the source code, Annotator turns documents into chunks, builds prompts, calls the language model, and passes the responses to a resolver that parses and aligns them. Results from multiple passes are merged. When spans overlap, the implementation keeps the extraction from the earlier pass and only adds non-overlapping results from later passes.
This behavior belongs in a product design document. extraction_passes=3 is not a free “try harder” switch. It can improve recall, but it also increases requests, cost, latency, and merge decisions. For a large corpus, compare precision, recall, cost, and latency on a small labeled sample before making multiple passes the default.
3. The provider factory separates model choice from extraction logic
The project uses a provider factory and entry points to discover model providers. Built-in providers include Gemini, Ollama, and OpenAI. ModelConfig accepts a model_id, an optional explicit provider, and provider_kwargs. The extraction program does not need to hard-code each vendor's initialization details.
This separation matters more than a raw list of supported models. A team can use a local Ollama model to test prompt alignment and data handling, then evaluate a cloud model for quality or throughput without rewriting the extraction and visualization pipeline.
Provider capabilities are not identical. The README documents output_schema support for Gemini and OpenAI scenarios, while the Ollama provider does not currently support that argument. OpenAI-compatible endpoints may also require an explicit provider and base_url. Do not mistake a common function call for identical guarantees across providers.
4. JSONL is an interchange format, not the review experience
lx.io.save_annotated_documents writes results to JSONL, and lx.visualize turns that file into a self-contained HTML view. The value of the HTML is not just presentation. It puts many extractions back into the surrounding source text.
JSONL is convenient for downstream data processing. The interactive page is convenient for analysts and domain experts. Keeping both views lets one result serve machine processing and human QA instead of creating a second review format.
Getting started with a verifiable local Ollama task
The following example uses the documented Ollama provider so that the first experiment does not require placing an API key in the source code. The prerequisites are Python 3.10 or newer, an installed Ollama runtime, and enough memory for the selected model.
Create an isolated environment and install the package:
python -m venv .venv
source .venv/bin/activate
pip install langextract
Start Ollama and download a model:
ollama serve
ollama pull gemma2:2b
Now define a small task: extract products, reported problems, and severity from a support conversation. The key is to require exact spans from the input rather than asking for a summary:
import langextract as lx
prompt = """
Extract product names, reported problems, and severity in order of appearance.
Use exact text from the input. Do not paraphrase or overlap extractions.
Put a short normalized label in attributes when useful.
"""
examples = [
    lx.data.ExampleData(
        text="The user reported a timeout while syncing photos in CloudBox; impact was high.",
        extractions=[
            lx.data.Extraction(
                extraction_class="product",
                extraction_text="CloudBox",
                attributes={"normalized": "CloudBox"},
            ),
            lx.data.Extraction(
                extraction_class="problem",
                extraction_text="a timeout while syncing photos",
                attributes={"normalized": "sync timeout"},
            ),
            lx.data.Extraction(
                extraction_class="severity",
                extraction_text="high",
                attributes={"normalized": "high"},
            ),
        ],
    )
]
text = "The user can log in to CloudBox, but photo sync still times out; this time impact is medium."
result = lx.extract(
    text_or_documents=text,
    prompt_description=prompt,
    examples=examples,
    model_id="gemma2:2b",
    model_url="http://localhost:11434",
)
# Keep only results that can be located in the input.
for extraction in result.extractions:
    if extraction.char_interval:
        print(
            extraction.extraction_class,
            extraction.extraction_text,
            extraction.char_interval,
            extraction.attributes,
        )
The first verification point is not whether the model returned three fields. It is whether each result has a char_interval and whether the span can be checked against the input. If Ollama is unstable, verify that the service is listening on localhost:11434, that the model has been pulled, and that the examples are verbatim, non-overlapping, and ordered.
Add JSONL and HTML after the small task works:
lx.io.save_annotated_documents(
    [result], output_name="extraction_results.jsonl", output_dir="."
)
html = lx.visualize("extraction_results.jsonl")
with open("visualization.html", "w", encoding="utf-8") as file:
    file.write(html.data if hasattr(html, "data") else html)
For a long document, use a URL or a document collection and tune the controls gradually:
result = lx.extract(
    text_or_documents="https://www.gutenberg.org/files/1513/1513-0.txt",
    prompt_description=prompt,
    examples=examples,
    model_id="gemma2:2b",
    model_url="http://localhost:11434",
    extraction_passes=2,
    max_workers=4,
    max_char_buffer=1000,
)
Start with a conservative max_workers. Local model throughput often becomes the bottleneck before the theoretical parallelism does. Measure memory, latency, and extraction quality before increasing concurrency.
Three common traps
Trap 1: treating grounding as fact checking
A char_interval shows that a span exists in the input. It does not show that the input is correct or that an inferred attribute matches a domain definition. A model can highlight “high risk” in a document while still failing your organization's formal risk policy.
A safer table design keeps source_text, char_start, char_end, extraction_class, attributes, and review_status as separate fields. Do not save only the final normalized value, or the team will need another model call to reconstruct the evidence later.
Trap 2: writing examples like summaries
If an example extraction is not a source span, or if several extractions overlap, the model may learn inconsistent annotation behavior. A prompt alignment warning is not harmless noise; it signals a broken data contract.
Start with one short example, then add another for an edge case: synonyms, repeated entities, adjacent entities, and documents with no matching extraction. Change one variable at a time so that a quality change can be attributed to the prompt, model, or resolver.
Trap 3: long-document cost is not just character count
Chunking, parallelism, multiple passes, and context windows all affect cost. More passes can increase recall while also increasing requests and merge complexity. A buffer that is too small can split a relationship; a buffer that is too large can make the model miss details.
Before production, create a small benchmark with manually labeled documents. Record precision, recall, the unaligned-result rate, average latency, and model cost for each configuration. Do not make multiple passes the default simply because they sound more thorough.
Where does LangExtract fit?
LangExtract is not a vector database, a complete RAG framework, or a replacement for OCR, database validation, or workflow orchestration. It is an extraction layer that uses an LLM while treating evidence alignment and human review as first-class concerns.
- Compared with traditional NER: it is easier to adapt with examples and can capture attributes and relationships, but it introduces inference cost, latency, and model variability.
- Compared with direct JSON generation: it adds source intervals, alignment status, and visualization, while provider and schema capabilities still vary.
- Compared with RAG: RAG retrieves context for generation; LangExtract turns text into traceable structured annotations. The two can be connected by indexing grounded extractions.
- Compared with annotation software: it can create machine pre-annotations and evidence markers, but high-risk data still needs human review.
Who should try it first?
I would start with teams that have a large text backlog, cannot accept source-less JSON, and want to preserve the option of switching between cloud and local models. Support tickets, research notes, contract clauses, product feedback, and structured clinical-note experiments are reasonable pilots.
It is not the first choice when a deterministic parser can solve a fixed-format conversion more cheaply. It is also insufficient when every inferred attribute must have an external truth guarantee. Sensitive documents need a data-transfer, provider, and retention review before any model is connected.
The README also states that LangExtract is not an officially supported Google product. Health-related use is subject to the terms linked by the project. Those notices are part of the adoption decision, not just footer text.
My assessment
The next competition in LLM extraction will not be only about who emits the prettiest JSON. It will be about who lets a team trust, inspect, and correct that JSON faster. LangExtract combines source grounding, chunking, provider abstraction, and visualization in a Python library that can start with a small task and scale only after quality is measured.
It does not remove model errors or perform domain validation. It does add the evidence chain that is often missing. The durable lesson is a design principle: whenever LLM output enters a database, decision process, or review queue, preserve its location in the source and make the next verification step explicit.
References